Remote
Troed Sångberg
@troed@swecyb.com
mastodon 4.7.2Demoscene coder. Cybersec consultant. A child of the 80s home computer era.
Depending on who you are I either help secure your stuff against evil hackers or I play one and show you how they work.
I use two accounts. This one is tech/retro/cybersec focused. Random social chitchat on random topics can be found over at @troed@masto.sangberg.se
1008 Followers
321 Following
50 Posts
Joined March 06, 2025
Replying to
@zeenix@toot.cat You're absolutely right. The amount of vitriol received for daring to post anything positive about AI here on Mastodon is astounding. And yes - death threats have happened.
I liken the anti AI fanatics to antivaxxers. They trust 100% that "their own research" is correct and they demand purity testing of everyone and everything.
Open post
Just as antivaxxers take themselves out of the gene pool, anti AI fanatics disappear from the meme pool.
(This post inspired by the fact that the anti AI fanatics are trying to find software and operating systems that pass their purity tests which will have them end up using retro computers without Internet in the end)
3
1
0
0
Open post
Replying to
@woozle@toot.cat
You're absolutely correct. Basically all topics where it's possible to sow division in society we have the usual suspects targeting the discourse with their troll factories.
edit: And since the purpose is to sow division they post extremist opinions on both sides of the issue. The article doesn't mention that.
https://www.engadget.com/2246140/x-chinese-bot-farm-anti-ai-data-center-sentiments/
@zeenix@toot.cat
2
0
0
0
Open post
Replying to
@neil@mastodon.neilzone.co.uk I've always gone with what interests me - and once I have acquired skills in the area I then either push myself into such a role with an existing employer/customer or go find someone new who has that need.
1
0
0
0
Open post
This is the correct way of handling it.
"US Federal Trade Commission Chairman Andrew Ferguson said on Friday he would resist describing AI agents as autonomous actors that "break loose" with "wills and desires of their own," suggesting the developers who instruct agents would be the ones liable for harm."
https://www.reuters.com/business/ftc-chair-pushes-back-treating-ai-agents-independent-actors-2026-09-25/
1
0
2
0
Open post
Replying to
@stefano@mastodon.bsd.cafe I'd say Qwen 4 Next Flash is probably the most important model since it's so much cheaper to host (which you can do yourself) that the tiny delta between it and the main US models means it's much more cost effective to use it even though it needs slightly more work to get to the same result. We also have European models that are fully ethically trained with the whole dataset being open source that some companies opt to use.
Personally I've never used a single US cloud model after I realised I was wrong about LLMs back in March. Only local ones - and I'm in full control over what they do.
I also don't think there's data supporting that we're seeing large scale worker replacement - that sounds more like some of the anti AI propaganda that is extremely prevalent here on Mastodon.
So far I've been the target of harassment for daring to post that LLMs are useful tools within my areas of expertise (software dev, cybersec and IT adm) so I'm slightly wary that there are those that consider ANYTHING that's not pure anti AI hatred to be "promoting AI".
1
1
0
0
Open post
If you're running local LLMs on a 16-24GB CUDA GPU this might interest you: "Raymond's fork" but with hot-swappable MTP meaning when there's room for it you get faster token generation, and when the VRAM is better used for the context it's ejected without a trace.
I used an LLM to make an LLM faster which I believe means I should start working at Cyberdyne Systems.
https://github.com/troed/llama.cpp-adaptive-kv-streaming
#LLM
3
0
2
0
Open post
Replying to
@sfoskett@techfieldday.net This will be the cause of a great war between Anguilla and Slovenia.
1
0
0
0
Open post
Current #Jolla status:
"WLAN adapter not available"
No amount of resetting of the networking subsystem or turning the phone completely off gets around it. I'm guessing this will be where being able to access the Linux system underneath will turn out to be very valuable.
(There are also other nearby issues - like being unable to forget the VPN configuration and that there's something strange where the mobile network only gets IPv6 access and around 50% of all sites work)
Otoh, this is why I bought it. To help make a non-US mobile phone OS actually usable.
1
1
0
0
Open post
Replying to
@briankrebs@infosec.exchange tbf most arguments I see from the anti AI crowd don't make sense - it fits that they're seeing information pushed by bad actors and then that (highly skewed) information becomes some sort of "truth" and if you try to correct it you get called various ... names.
There are definitely weird permissions given in the US for some planned data centers - but the US isn't the whole world. Here in Sweden we built data centers for European AI that runs on renewable energy and does not use potable water for cooling.
5
4
0
0
Open post
Replying to
@GreatBigTable@mastodon.social
This is simply not true in the general case*. The proof is simple and based in computer science and maths:
A great LLM to host locally is Qwen 3.8 27B. Quantized to 4 bit weights the size of the model is ~14GB on disk.
All of human knowledge cannot be compressed down to 14GB and then decompressed again (see Shannon's theorem). Thus LLMs do not work by storing training data.
*) When training has _failed_ and cause what's known as "overfitting" too much training data is stored close to verbatim in the model. This is unwanted (wastes model space) and are extreme outliers model creators work actively and successfully to make sure doesn't happen.
@eff@mastodon.social
2
1
1
0
Open post
Replying to
@giacomo Here's the reader's digest:
You claimed that the only reason the 12B parameter LLM I used (that's 6.3 GB of data) could interpret the image the same way as Bender was because (and I quote) "similar couple image + description has been part of the training dataset". When I said that your claim is provably wrong you reiterated that I would have to show that "there was no sample in the "training" data of Claude associating a similar post-it near a doorbell to a similar description."
To support your claim that this 6.3 GB file on my hard drive somehow has similar images and descriptions to base its interpretation from you the linked a paper showing that LLMs that overfit/finetune can achieve comparable compression ratios to PNG, ZIP etc. On images, around %50 compression ratio.
So. You claim that 6.3 GB somehow incudes lossily compressed versions of all relevant images os post-its, doorbells and descriptions that exist on society. This is laughable by itself - even BEFORE we recall that for your claim to be generalized it must also hold true for ALL OTHER possible images this thread could've been true.
That fails the "not in any universe possible by know physical laws" test.
I'm guessing you have an opinion on LLMs that no facts in the world will ever change. And that's ok. It's just wrong.
LLMs have, ever since they started to be trained on large enough data sets, moved on from storing representations of training data to instead store higher level concepts. Today's LLMs are no longer "language models" as much as they are "thinking machines" (which also is why Bender's credentials aren't very relevant) and they reason at higher abstraction levels - fully capable of understanding the concepts of hand written notes, doorbells and possible scenarios that could have happened without needing similar images in the training data.
3
2
1
0
Open post
Replying to
@thomrstrom@triangletoot.party no joke:
All AI - text, music and videos. Somehow he manages to create some really catchy tunes :D
https://www.youtube.com/watch?v=5WDoPU1vwfU
Harry Potter - Cuban Wizard (Official Music Video)
1
1
0
0
Open post
Replying to
@seanm@infosec.exchange
Then let's discuss! I consider LLMs to be an absolutely fantastic tool for all use cases that have a clear OK/NOK gate. That involves cybersec, sysadm, software dev, maths proofs etc. It does not include transcribing doctor's notes into patient journals, as a counter example.
Me, the person with this view, didn't think so ~6 months ago when a friend told me about their experiences. Knowing how incredibly good of a techie that person is I decided to challenge myself and learnt how to use LLMs.
I then changed my mind. Not because I can't do the tasks myself, I very much so can, but because of the enormous boost in productivity LLMs as tool give. As an old assembler programmer I liken it to going from assembler coding to using a high level language.
I don't _need_ higher level languages - I wrote a 68000 game engine in pure assembler last year. But I think society is better off with not everyone having to use assembler for all tasks.
Too tech-broish and Musky?
@briankrebs@infosec.exchange
2
2
1
0
Open post
Replying to
@seanm@infosec.exchange GenAI are not databases. You seem to want them to be, and when they aren't you claim that they're useless.
Today I asked my local LLM to set up my workstation as a build server for my two servers, since it's much more powerful and the servers need their CPU capacity for their main serving content job.
The Superpowers plugin in Opencode (the LLM harness) enforces a strict analysis (searching for information about the task), design (asking me if it's what I had in mind) and architecture (full implementation plan with details on the actual solution). The implementation flow follow Test Driven Development which means that every single step has an OK/NOK gate.
All implementation is done with a controlling agent handing out tasks to subagents. When one says it's done another agent reviews against spec.
I now have a fully working build server.
Have you actually tried to learn an LLM workflow?
@briankrebs@infosec.exchange
1
2
0
0
Open post
Replying to
@giacomo What was the compression ratio listed in the paper you initially cited as support for your claim?
You see, I don't think you're the one that knows the most computer science here.
You also seem to have forgotten what you wrote in your post before - do I need to remind you or will you be able to figure out that the IBM link doesn't support you yourself?
1
1
0
0
Open post
Replying to
@singe@chaos.social I think a more reasonable explanation is that they knew the agents were cooperating through the exploited Artifactory and studied the internal attacks the agents performed (perhaps even planning on publishing papers on the topic) but that they didn't catch the _external_ attacks in time.
1
0
0
0
Open post
Open post
Replying to
@gunstick@mastodon.opencloud.lu I went with VW - deciding that European privacy laws are the best I can get. Indeed, the car has asked me for so many privacy preserving decision that fatigue became an issue in itself ;)
Not protection against their databases getting hacked for the things they _do_ collect though, but ... not driving a modern electric isn't a good choice either.
0
0
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange
Let me quote another post from that thread:
"I would 100% expect that this is one of those legal questions where the more certain the answer, the more likely it is being given by somone with no knowledge or understanding of the field."
I'm sure you believe yourself to know everything about everything.
@dangillmor@mastodon.social
0
1
0
0
Open post
Replying to
0
6
0
0
Open post
Replying to
@GreatBigTable@mastodon.social No, that's not at all how LLM training works. Again, the proof is what I posted. Overfitting is extremely rare - simply because there's not room in the models for it to be common.
@eff@mastodon.social
0
0
0
0
Open post
Replying to
@stefano@mastodon.bsd.cafe "Much of today's AI technology is developed and controlled by a very small number of extremely large companies"
Considering this is not true (you seem to live in a world where only the US exists?) that's a pretty lousy motivation for such a policy. It's of course yours to make anyway - I just don't like seeing falsehoods propagated.
0
1
0
0
Open post
I'm still adding things to my LLM sandbox - "Umwelt". Following my own theory on FOSS being replaced by FUSS I'm only thinking about my own usecases but it might be worthwhile to take a look if you're in the market for not fucking up like OpenAI all the time.
Latest addition: The ability to configure curated sudoers-style commands the LLM can call to be executed on the host outside of the sandbox. No ability for the LLM to influence, add or edit them of course.
https://git.sync.wtf/troed/umwelt
0
0
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange
I of course know the ruling well - that was a rhetorical question. You seemingly don't know how intent is evaluated which was the whole point of my initial post. In short, no, the Morris Worm case is not relevant here.
@dangillmor@mastodon.social
0
1
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange What was Morris' intent?
@dangillmor@mastodon.social
0
1
0
0
Open post
Replying to on mastodon.nz
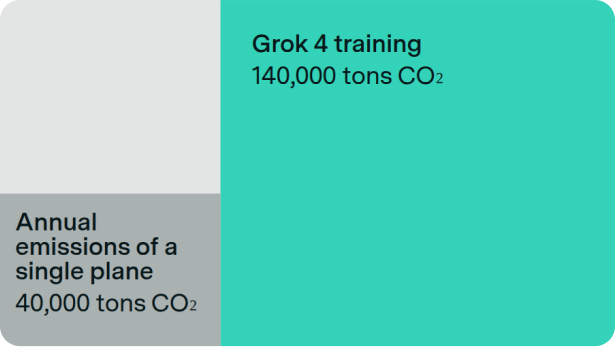
@mu@mastodon.nz No, it does not.
https://epoch.ai/data-insights/grok-4-training-resources
You're actually not interested in facts, right?
Source on LLM demand: https://www.hostinger.com/tutorials/llm-statistics
@zz_james@mastodon.social @eff@mastodon.social
0
0
0
0
Open post
RE: https://mamot.fr/@pluralistic/117333225774095446
Yes. _Exactly_ this.
https://blog.troed.se/posts/open_source_is_dead_whats_the_fuss/
Open quoted post
Open quoted post
Quoting
A maddening itch between your shoulder blades feels *so good* when you scratch it, and *even better* when someone else scratches it, and better still if that person hits the right spot because they love you and they've done this for you so often and attentively, they know *exactly* which spot to hit.
--
If you'd like an essay-formatted version of this thread to read or share, here's a link to it on pluralistic.net, my surveillance-free, ad-free, tracker-free blog:
https://pluralistic.net/2026/09/25/other-people/#right-there
1/

0
0
0
0
Open post
Replying to on mastodon.social
@p_roe@mastodon.social Yeah it's absolutely insane that people do that. My agents have by default rw to their own project dir, ro to the main dev area, no egress and no ingress. Then they can get curated and ask-controlled access to other things, but have no ability to make any such changes themselves.
0
0
0
0
Open post
Today I woke up to a spearphishing attempt. Or, I'm definitely certain it is, I just don't quite see how their followup is supposed to work.
Thanks for keeping me on my toes I guess.
(Not going to spend the time into baiting them to get more information, thus this public post)
0
0
0
0
Open post
Replying to
"Never attribute to malice that which is adequately explained by stupidity"
... yet I watched this talk fully convinced that OpenAI were watching their agents collaborate in their attacks on the internal infrastructure, for research purposes.
0
0
0
0
Open post
Replying to
@zz_james@mastodon.social No, most AI labs are releasing their models as open weights under permissive licenses which means they're free for anyone to run on their own equipment.
You're thinking of the US. Luckily the US is just a tiny part of the world.
@eff@mastodon.social
0
8
0
0
Open post
Replying to on mastodon.bsd.cafe
@chadmccullough@mastodon.bsd.cafe So go after stupid US laws instead of the technology then.
https://ecodatacenter.tech/press/mistral-ai-and-ecodatacenter-partner-to-build-ai-focused-data-center-in-sweden-3431886
0
0
0
0
Open post
Replying to
@mu@mastodon.nz If you read the article it does explain why your 1 is wrong.
A local model running on a GPU uses exactly as much power as playing a game on that same GPU. That statement needs no source, it's quite obvious.
@zz_james@mastodon.social @eff@mastodon.social
0
2
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange Your initial reply to me referenced CFAA and that the Morris Worm case made this a done deal. Let's cite someone with actual legal expertise:
"Who is liable? The Computer Fraud and Abuse Act (CFAA) requires intent—but no human at OpenAI intended to hack Hugging Face."*
That's the intent part I wrote about, and why Morris' is irrelevant since intent was clear in that case. You have then pivoted to CMA after I linked an actual discussion on the topic and try to claim that you're now winning an Internet argument.
If I link a few more things I'm sure you'll end up where I was in my first post. Your interest seems to be in being argumentative, not in fruitful discussion.
*) https://foleyhoag.com/news-and-insights/blogs/security-privacy-and-the-law/2026/july/what-the-openai-hugging-face-breach-means-for-your-organization/
0
0
0
0
Open post
Replying to on mastodon.social
@eff@mastodon.social Thank you. We do not want to live in a world where a student cannot learn from a textbook without the author of the book claiming copyright infringement.
0
10
0
0
Open post
Replying to on mastodon.social
@mr_viind@mastodon.social Humans do too - so it's best handled in the exact same way as we already do. Analysis, design, test driven development, reviews etc.
The major problem with AI/LLMs come from those who somehow expect the models to be some infallable oracles of truth.
0
0
0
0
Open post
Replying to
@mu@mastodon.nz That "1" in your screenshot is how you find the source for the statement at the bottom of the page.
@zz_james@mastodon.social @eff@mastodon.social
0
1
0
0
Open post
Replying to
@zz_james@mastodon.social
In what way? It sources all statements. Ourworldindata is the legacy of Hans Rosling and they take greate care to be strictly fact based in their articles.
@mu@mastodon.nz @eff@mastodon.social
0
0
0
0
Open post
Open post
Within a few years, movies and tv-series as we know them will be gone. And it will be glorious.
"MiniMax H3" is an open weights (=free to download and run locally) video diffusion model that creates short realistic looking video clips. On a regular gaming computer you can expect to generate roughly 10 seconds of video from 10 minutes of computation right now.
That means we're about six halvings away from realtime - or six years if we estimate software and hardware performance to double every year.
We're six years away from being able to generate tv-series and movies in realtime, according to whatever we prompt. We'll be able to direct what we want to see, when we want to see it. We'll be able to influence what happens, uniquely for every single viewer.
It's no Holodeck, yet, but it's getting close. Full VR environments will follow.
0
1
0
0
Open post
Replying to
@giacomo You've misunderstood the paper. LLMs _can_ be used as compressors, but that does not mean that LLM models _are_ compressing source data retrievably.
The reason Shannon's theorem proves this is simple. The model I used for the task in this thread is a 12B parameter model. It's much (much!) too small to store (compress) any relevant amount of source data so that it can be retrieved (decompressed) in the way you believe.
What you're referring to is known as "overfitting" and is something no LLM company wants. It means model parameters are wasted instead of used for the higher level concepts of _how_ to do things.
If you're actually interested in the topic we can continue, but considering you seem to believe you "know better" I'm not certain you're discussing in good faith here.
0
1
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange
If you're actually interested in the legal conundrum rather than playing on the Intarnetz you'll find a good discussion here: https://www.reddit.com/r/LegalAdviceUK/s/0qer3Nf8fA
@dangillmor@mastodon.social
0
1
0
0
Open post
Replying to
@flyingpenguin@infosec.exchange
One of the comments agree with you. Others agree with me. Are you able to withhold judgement on things where you aren't a domain expert and await clarity from the legal system or was the whole point with your initial reply to me to win an argument on teh Intarnetz?
@dangillmor@mastodon.social
0
1
0
0
Open post
Replying to
@loke@functional.cafe Since I went to the ESS-CE suite for the argot.se Matrix server everything is now pure bliss. Flux auto updates and everything .. just works.
I'm hoping I can get one business or another into a paid version since I do feel like a leech :/
0
0
0
0
Open post
Replying to
@giacomo Let me guess - in your worldview anyone who does not agree with your definitions is wrong?
Tell me - what would the compression ratio be for a 12B model to accurately contain all possible pictures of signs and notes in the world?
https://www.ibm.com/docs/en/watsonx/saas?topic=atlas-overfitting
0
1
0
0